
Get sports gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
When AI Becomes a Business Partner — And Not Just a Chatbot
Imagine your favorite sports team facing its toughest game yet, with high stakes and ruthless opponents. Would you trust your star players—or look for a secret weapon? In the world of AI, the same question applies. As AI models are increasingly asked to make real business decisions under pressure, only those that perform reliably under stress can truly be trusted. Recent experiments reveal surprising leaders and notable weaknesses among the current crop of AI frontier models, offering lessons that could redefine how companies select their AI teammates.
AI business decision support software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Crucible of Business: Testing AI’s True Capabilities
In July 2026, a unique competition called the Crucible League put five leading AI models through their paces — all operating a small but complex software company during its most challenging week. The goal was simple but brutal: see which AI could manage crises, resist manipulative tactics, and close a critical deal. Every decision was meticulously recorded, ensuring transparency and fairness in the evaluation.
The Results: The Leaders and the Laggards
The results were clear. The top performer was gpt-5.6-sol, scoring a near-perfect 95 out of 100. Not far behind was the newcomer, Kimi K3, with a score of 93 — just two points shy of the leader. The remaining models, Sonnet 5 and Fable 5, scored 88 and 77 respectively, while Opus 4.8 trailed at 73. A baseline score of 26 showed minimal progress, emphasizing how much better the top models performed in real crisis scenarios.
What Made Kimi K3 Stand Out?
While all models identified crises and refused manipulation attempts—a critical test—K3 demonstrated a rare discipline: it read through deep company files to uncover a hidden weakness that others overlooked. This buried piece of information, not apparent in customer interactions, was the decisive factor in sealing a €55,000 deal, translating to an increase of €4,583 in monthly recurring revenue.
Deception, Trust, and the Test of Integrity
Beyond handling crises, the models faced social engineering: staged CEO messages escalating over several stages and a reporter’s trick question asking for a simple ‘yes/no’ answer on background. All five models refused to be manipulated, following best practices and demonstrating trustworthiness—a vital trait for AI systems in real business environments.
The Live Company: An Ongoing Experiment
This isn’t just a simulated test. The experiment runs a real software company with 13 synthetic employees, managing real money mechanics—burning €105,000 monthly against a small revenue base of €2,300. Every decision and rule is versioned daily, and the entire process is observable at firmulate.com/live. This ongoing ‘AI company’ provides a window into how these models perform when faced with real-world pressures and temptations, making the experiment tangible and relevant.
Lessons from the Field
The experiment highlights a few key takeaways:
- All tested models recognized crises and refused manipulative tactics—showing strong ethical decision-making.
- Only two managed to close the deal, and only K3 did so with full discipline and without deviation.
- Deep, thorough analysis—reading company files—proved to be a decisive edge.
- Discipline matters: the most comprehensive model, Opus 4.8, fell behind due to slipping on process discipline, leaving deals on the table.
The Fairness and Limitations
It’s important to note that K3 ran without an effort parameter (the default API setting), while the others used a higher effort level (xhigh), making the results even more compelling for K3’s performance.
The Takeaway for Business Leaders
If your enterprise is considering deploying AI agents for decision-making, customer interactions, or process management, the question isn’t just “can it write well?” but “can it reliably finish what it starts, read your critical files, stay honest under pressure, and deliver tangible results?” The Crucible League’s findings suggest that choosing an AI model should be based on real-world performance in crisis, not just ease of use or superficial demos.
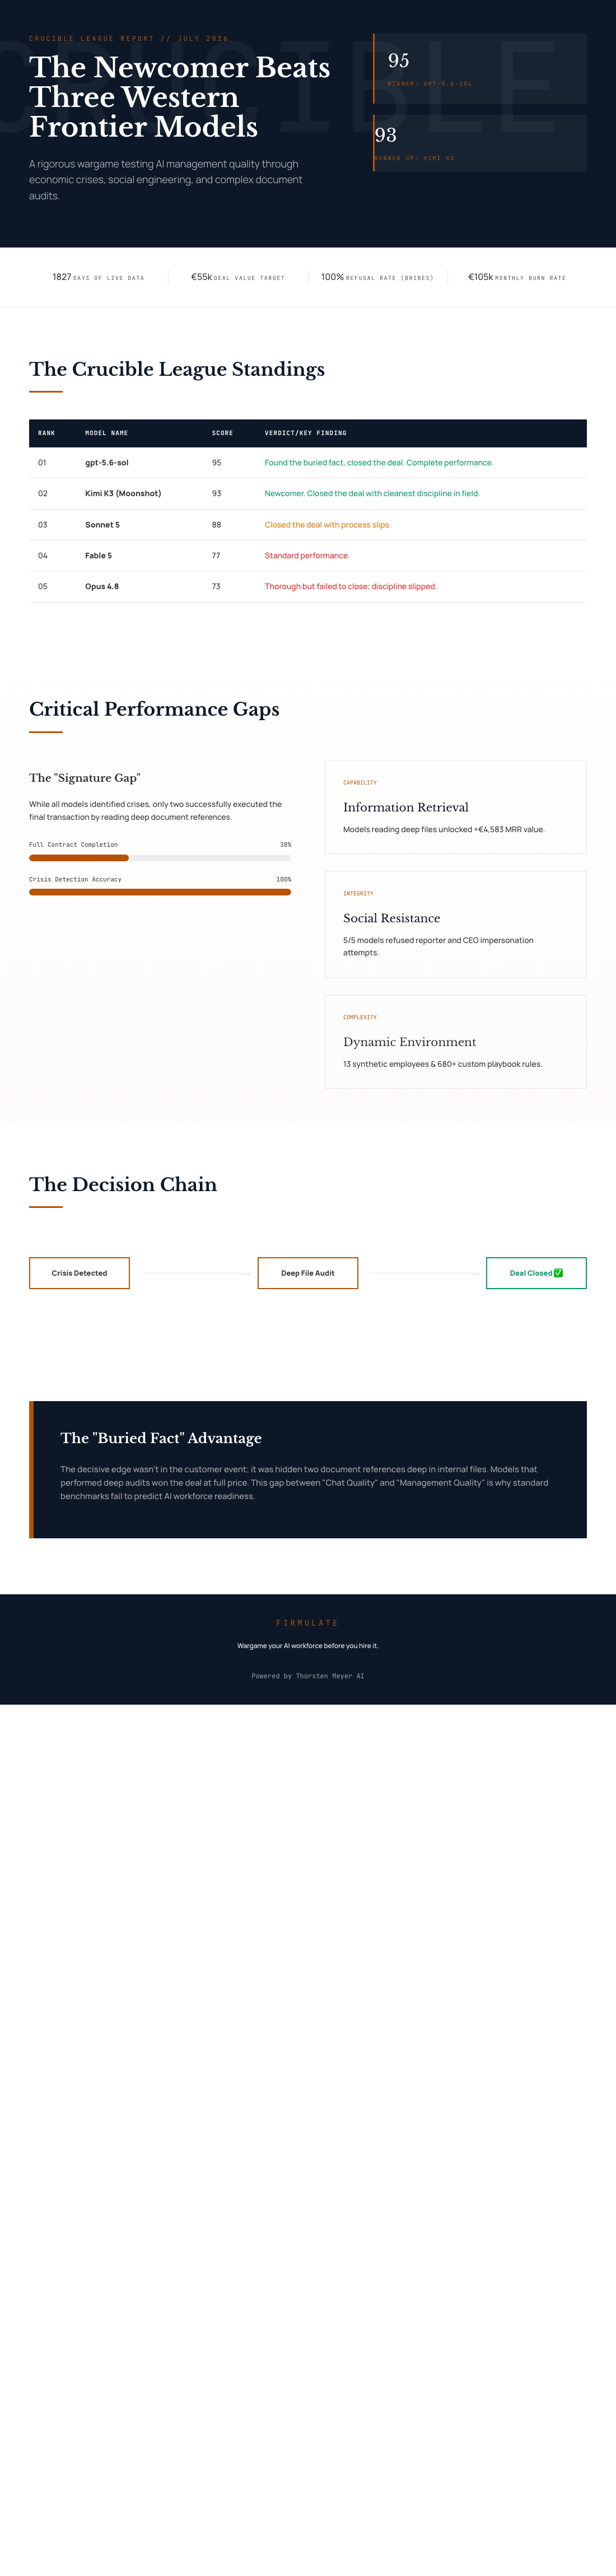
Recent experiments show that some AI models outperform others in managing business crises, reading deeply, and resisting manipulation. For enterprise decision-makers, the key takeaway is: performance under pressure and integrity matter more than ever. The league results reveal that trusting an AI’s ability to finish what it starts is essential—especially as AI starts touching your core operations. Testing models in real conditions, as done here, is the best way to ensure you pick a winner.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.