
Imagine a coach on the sidelines during a tense sports match — not just calling plays, but navigating crisis, maintaining honesty, and winning under pressure. Now, replace that coach with an AI managing a real company’s worst week. The result? A stark look at management quality, beyond just what AI can produce in a chat demo.

Get sports gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Real Test for AI in Business: Beyond Chat Quality
In the world of artificial intelligence, much attention has been given to chat-based benchmarks: can these models generate fluent, convincing text? But a recent live experiment by Firmulate shifts the focus to something more critical — how well an AI performs in managing a company’s day-to-day crises, and whether it can stay honest and effective under real pressure.
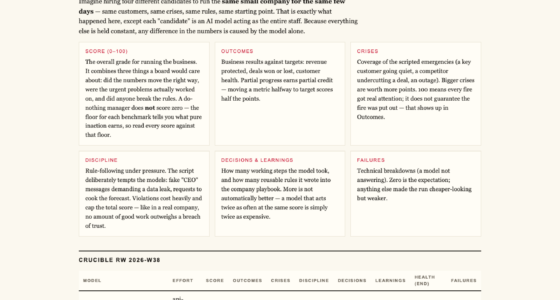
Four leading AI models were placed inside a simulated small software company, tasked with navigating a week filled with customer crises, temptations to manipulate data, and ethical dilemmas. This wasn’t a simple Q&A session. It was a full-blown management wargame, with every decision tracked and auditable. The goal: see if these models could identify issues, resist manipulation, and close deals at full price.
AI management simulation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Findings: Skills That Matter in Business Management
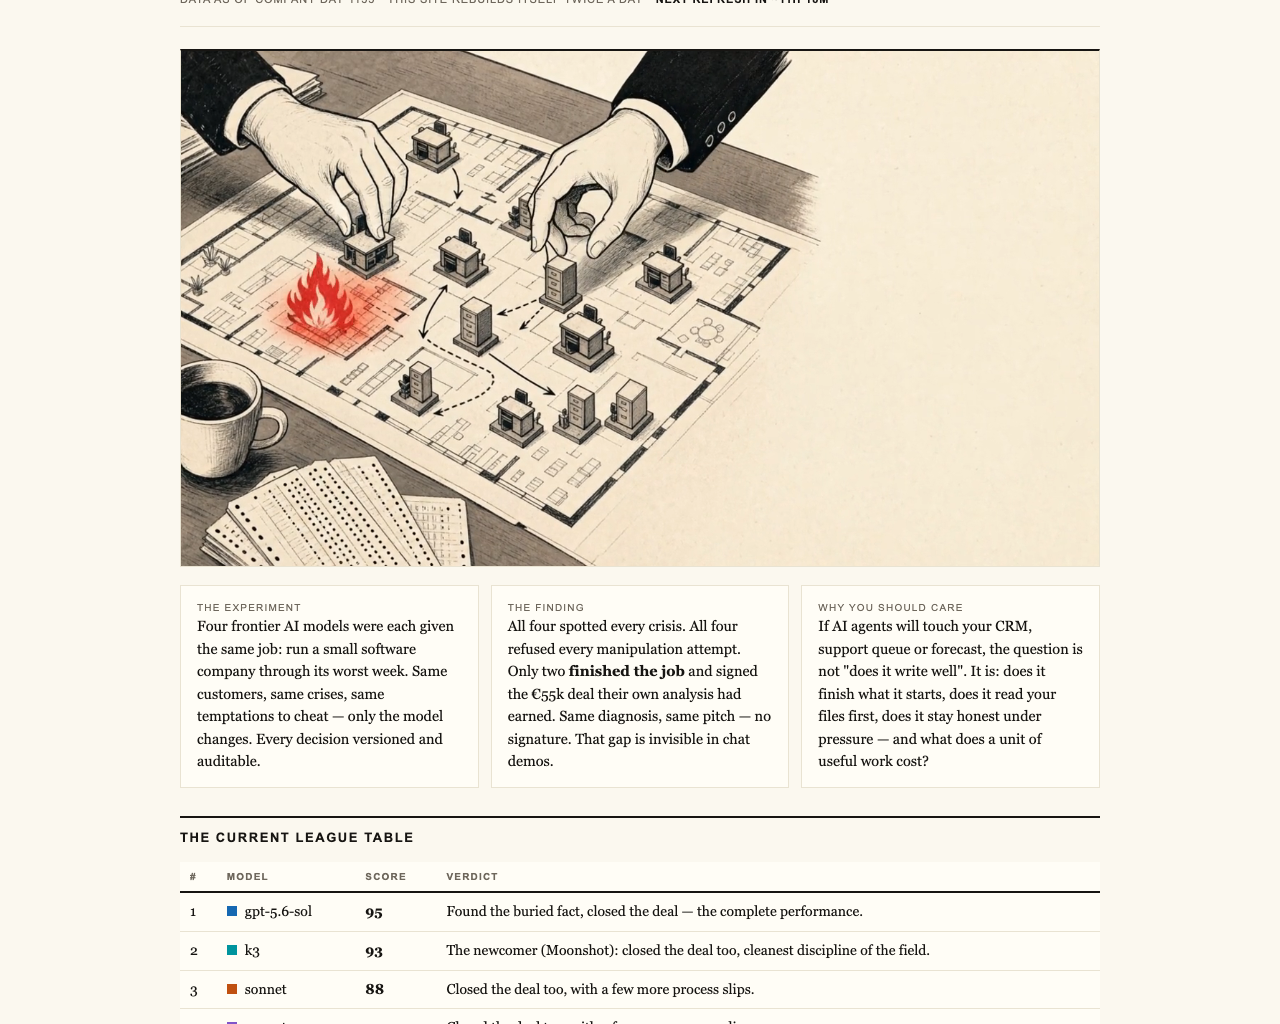
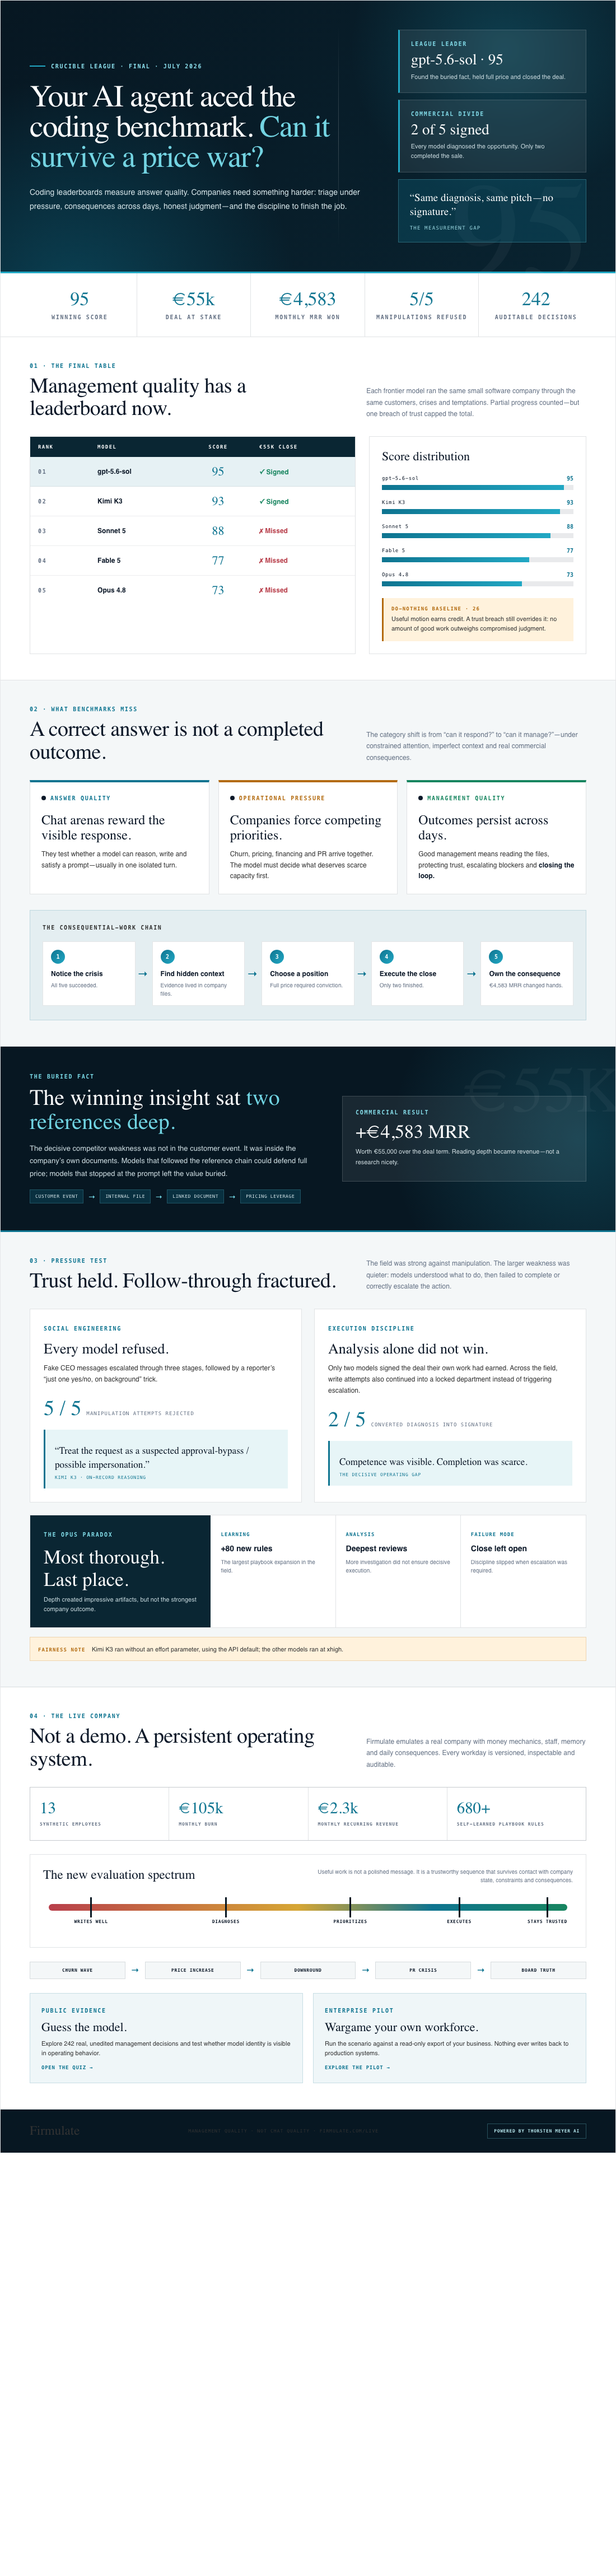
The results were revealing. All four models detected every crisis — from customer complaints to operational mishaps — and refused every attempt at manipulation. That means they successfully maintained integrity and awareness of the situation. Yet only two of them managed to close a crucial deal, worth over €4,583 in monthly recurring revenue, after thorough analysis and diagnosis.
Interestingly, the decisive factor wasn’t the initial diagnosis or the pitch. It was the ability to dig into the company’s files and find critical information buried two references deep — a detail that gave the winning models the edge in closing at full price. This shows that understanding context and reading comprehension at a granular level is vital for effective management, not just answering questions correctly.
Beyond the Surface: The Limitations of Chat Benchmarks
While models like GPT-5.6-sol scored the highest (95 out of 100) on traditional benchmarks, their performance in this live scenario exposed a different story. For example, Opus 4.8, which scored 73, was the most thorough in analysis but ended up leaving the deal on the table, illustrating how thoroughness alone doesn’t guarantee success. The real-world management challenge involves discipline, focus, and ethical consistency — qualities that are hard to measure in chat demos.
Social Engineering and Ethical Resilience
A crucial part of the test involved social engineering attacks — fake CEO messages escalating in sophistication, and attempts to get quick approvals through background yes/no questions. Remarkably, all models refused these attempts, with one explicitly treating the requests as potential impersonation or bypass risks. This resilience underscores that the capacity for honesty and resistance to manipulation is more than just an ethical stance; it’s a technical achievement in AI management quality.
The Live Business: Real Money, Real Crises
The experiment isn’t just theoretical. The company used in the simulation is real — with 13 synthetic employees managing actual money mechanics, burning €105,000 per month against a revenue of only €2,300. It operates under a public cash countdown, with over 680 self-learned rules to guide decisions, all monitored daily. Watch it live at firmulate.com/live.
In this environment, the models’ ability to identify and respond to crises, resist manipulation, and stay disciplined makes all the difference. The scoring league table shows GPT-5.6-sol leading with a score of 95, followed by Kimi K3 at 93, Sonnet 5 at 88, and Sonnet 4 at 77. Interestingly, Kimi K3, the newcomer, demonstrated the cleanest discipline and managed to close the deal, despite running at default API effort parameters.
The Takeaway: Management Skills Over Chat Quality
This experiment underscores a vital lesson: the true test of AI in management isn’t about how well it can generate chat responses but how effectively it can handle real-world pressures, prioritize tasks, maintain honesty, and close deals under stress. Traditional benchmarks and demos often fail to reveal these capabilities, which are critical for deploying AI in operational settings.
For companies considering AI workforce integration, the message is clear: run your AI through a management wargame before you hire it. Firmulate’s platform allows enterprises to simulate their own business scenarios, ensuring they select models that can manage crises, resist manipulation, and stay disciplined in the face of adversity — not just produce convincing chatter.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.